Spark vs Hadoop vs DuckDB vs Polars
·11 mins
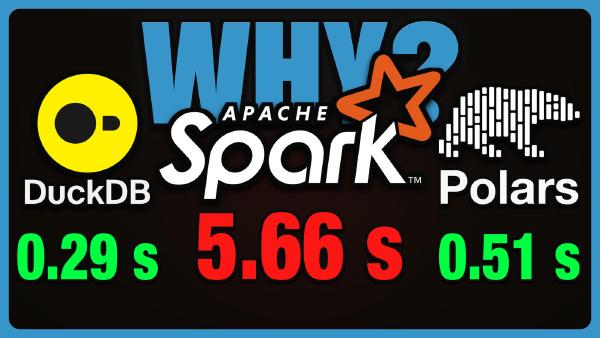
One SQL query on 41 million New York taxi trips in an Iceberg table takes 0.29 s with DuckDB, 0.51 s with Polars, and 5.66 s with Spark, all on one laptop. In this chapter, we see how DuckDB and Polars use every core of one machine, how the Google File System, MapReduce, and Hadoop store and process data on many machines, and how Spark works: its cache and lineage, the driver and executors, the query plan, tasks, stages, and shuffles. We also see when one machine is enough and when Spark is worth its costs.